Running trillion-parameter LLMs on Mac Studio clusters with MLX
Apple researchers demonstrate how to run the 816B Muse Spark Open model across four Mac Studios using MLX and RDMA over Thunderbolt.
Apple Machine Learning Research has published a technical deep dive showing how to run frontier-class large language models locally on Apple Silicon. Released on October 15, 2026, the report details how the open-source MLX framework leverages unified memory and new networking drivers to handle models with nearly a trillion parameters.
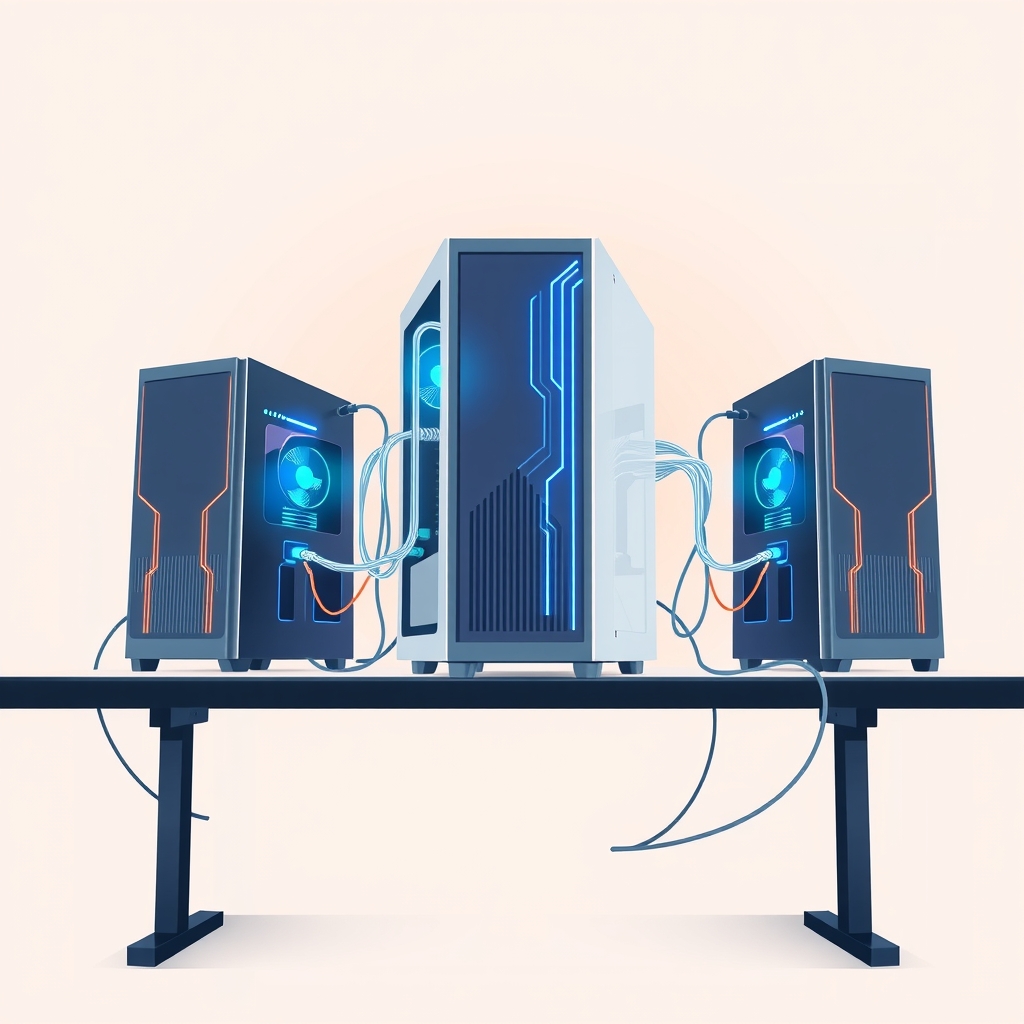
The team successfully ran the Muse Spark Open model, which contains 816 billion parameters, on a cluster of four Mac Studio computers. By using pipeline and tensor parallelization strategies over Thunderbolt connections, they achieved generation speeds exceeding human reading rates while maintaining low power consumption.
What happened
The research focuses on the capabilities of the newly released M5 Ultra chip and the latest version of the MLX array framework. Previous work highlighted the GPU Neural Accelerators in the M5 architecture, but this post demonstrates practical inference performance for massive models. The authors benchmarked three specific models: Muse Spark Open (816B parameters), Mistral Medium 3.5 (128B parameters), and Qwen 3.8 (27B parameters).
On a single Mac Studio with 512GB of unified memory, the smaller dense models fit comfortably. However, Muse Spark Open requires significantly more memory. Even in 4-bit NVFP4 precision, the model footprint is about 493GB, leaving little room for intermediate computations. To solve this, the researchers distributed the workload across multiple machines using Remote Direct Memory Access (RDMA) over Thunderbolt 5, a feature introduced in macOS 26.2.
The benchmarks measured time to first token (TTFT), generation throughput, and peak power usage. For the largest model, the team used a cluster of four Mac Studios connected via Thunderbolt cables. This setup allowed them to split the model’s layers or weights across devices, enabling inference that would otherwise be impossible on desktop hardware.
How it works
MLX uses two primary strategies to distribute large models across multiple computers: pipeline parallelization and tensor parallelization. Pipeline parallelization splits the model by depth, meaning one machine handles the first half of the neural network layers and sends the output to the second machine for the remaining layers. This approach is simple to implement and incurs low communication overhead because only intermediate outputs are exchanged between nodes.
Tensor parallelization splits the model by width, distributing fractions of each layer across all machines. This method allows for greater compute parallelization but requires frequent communication for every token and layer. To make this viable, MLX relies on jaccl, a set of communication collectives built on top of the low-latency RDMA-over-Thunderbolt driver. This ensures that the small, frequent data exchanges required by tensor parallelization do not become a bottleneck.
The M5 Ultra chip plays a critical role in this architecture. Its GPU Neural Accelerators provide dedicated hardware for matrix multiplication, which accelerates compute-bound tasks like calculating the time to first token. Additionally, the M5 Ultra offers 1.2 TB/s of unified memory bandwidth, a significant increase from the 819 GB/s available on the previous M3 Ultra. This bandwidth directly improves generation speed, which is memory-bound.
Key details
- Muse Spark Open is an 816 billion parameter mixture of experts model evaluated in NVFP4 precision, with only 42 billion active parameters during inference.
- A cluster of four Mac Studios with M5 Ultra chips achieved over 36 tokens per second for Muse Spark Open at a context size of 8,192 tokens.
- The M5 Ultra delivers up to 4.6× faster time to first token compared to the M3 Ultra for compute-bound workloads due to GPU Neural Accelerators.
- Peak power consumption for LLM inference on a Mac Studio with M5 Ultra is approximately 300 watts, significantly lower than many server-grade alternatives.
- MLX v0.30.1 and later supports
jacclfor RDMA over Thunderbolt, enabling low-latency communication between Mac Studio units. - Pipeline parallelization can be up to 1.8× faster than a single node for prefilling very large contexts (65,536 tokens) by overlapping computation chunks across machines.
Why it matters
For software engineers and AI researchers, this development lowers the barrier to experimenting with frontier-class models. Running an 816 billion parameter model locally means data never leaves the private environment, addressing significant privacy and security concerns associated with cloud-based APIs. It also allows for rapid iteration on fine-tuning and inference methods without waiting for cloud resource allocation or dealing with egress costs.
The efficiency of Apple Silicon also changes the economics of local AI infrastructure. With peak power usage around 300 watts, a Mac Studio can operate in standard office or home environments without specialized cooling or power infrastructure. This makes it feasible for small teams or individual developers to maintain high-performance inference clusters that are both powerful and energy-efficient.
Furthermore, the support for large context windows is crucial for agentic workflows. Coding assistants and complex reasoning agents often require context sizes of 65,536 tokens or more. The ability to process these large contexts quickly on local hardware enables more sophisticated autonomous agents that can understand entire codebases or lengthy documents in real time.
What you can do
- Install the latest version of MLX (v0.30.1 or later) to access support for RDMA over Thunderbolt and the
jacclbackend. - Use the
mlx_lm.benchmarktool to measure time to first token and throughput for your specific models and context sizes. - Connect multiple Mac Studio units with two Thunderbolt cables per pair to double link bandwidth for distributed inference.
- Experiment with pipeline parallelization for simpler setup and low communication overhead when splitting models across two machines.
- Use tensor parallelization across four machines for maximum compute parallelization, ensuring you configure the Thunderbolt mesh correctly.
- Enable the
MLX_METAL_FAST_SYNCH=1environment variable to reduce communication overhead between CPU and GPU during distributed jobs.