Reproducing OLMo 3 7B on TPUs reveals hidden data loader bugs
A Google case study reproduces AI2's OLMo 3 model on TPUs, matching performance metrics while uncovering critical data sharding errors that masked memorization as improvement.
Daily coverage of AI, developer tools and infrastructure. Each story explains what happened and why it matters, with a link to the original source.
A Google case study reproduces AI2's OLMo 3 model on TPUs, matching performance metrics while uncovering critical data sharding errors that masked memorization as improvement.
Google Developers Blog details autofinetune, an agent-driven system that automates hyperparameter tuning for SFT and RL post-training on Cloud TPUs.
Google Developers Blog outlines how behavioral evaluations provide actionable feedback for AI agent development, moving beyond opaque end-to-end benchmark scores.
Google analyzed winning entries from its 2026 AI Agents Challenge to identify four reusable engineering patterns for building robust multi-agent systems.
Google details how native TPU support in vLLM enables elastic scaling and high-precision embedding inference for Qwen3 models.
HeyGen and Google Cloud engineers detail how they ported the Avatar IV video generation pipeline to Trillium v6e TPUs, achieving a 1.86x speedup through kernel optimization and parallelism strategies.
Google's 2026 guide details using LiteRT to run Gemma models on Raspberry Pi 5, achieving real-time inference for robotics and edge agents without cloud dependency.
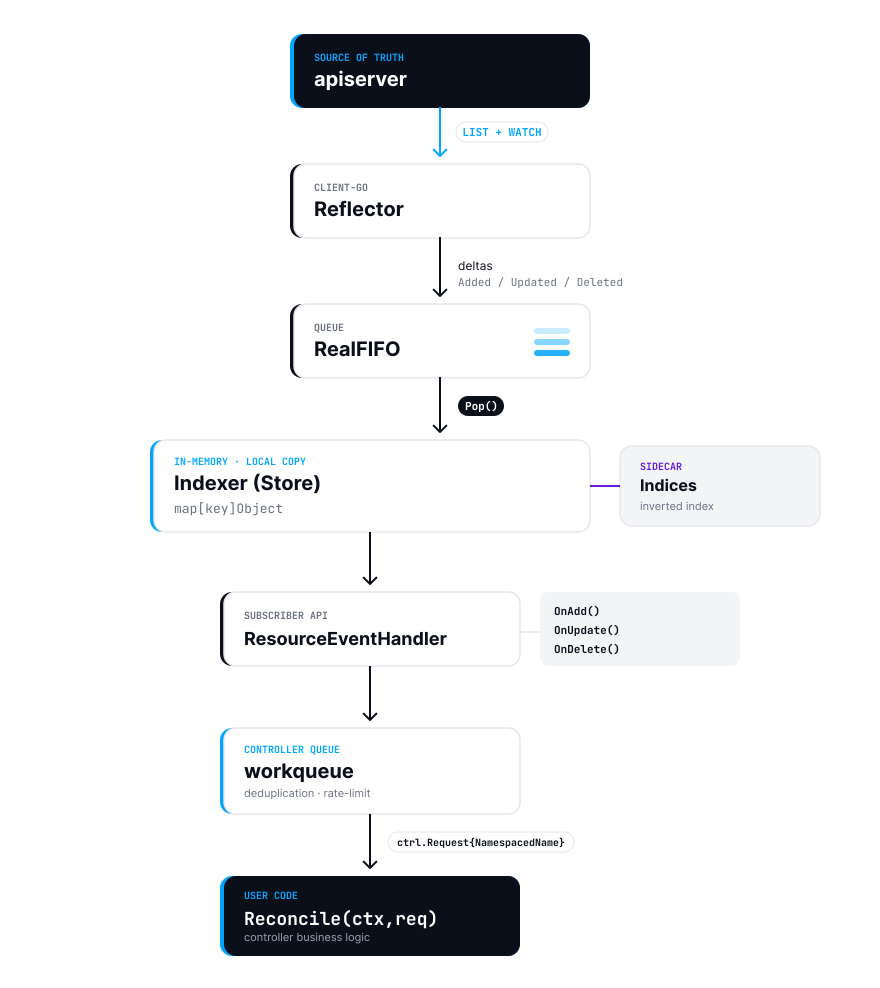
A deep dive into the list-watch pattern and local caching in Kubernetes controllers, explaining why reads are cheap but consistency is eventual.
A 2026 guide details how to replace Kubernetes Dashboard with Headlamp, shifting from form-based deployments to YAML-driven workflows and multi-cluster management.
A deep dive into kernel parameters like swappiness and watermarks reveals how to safely enable swap in Kubernetes v1.34 without triggering OOM kills.
Kubernetes lacks native support for partial device failures, forcing engineers to build custom remediation logic for expensive AI and ML training jobs.
A new specification allows container images to declare host OS and hardware requirements, enabling automated validation before scheduling in Kubernetes clusters.
The Kubernetes project released the Gateway API Inference Extension to standardize routing for generative AI workloads, reducing latency and improving GPU utilization.
Kubernetes v1.33 introduces a new verification mechanism to prevent unauthorized pods from reusing private container images already present on a node.
Kubernetes v1.33 adds streaming encoding for List responses, reducing kube-apiserver memory usage by up to 20x during large dataset fetches and improving cluster stability.