Optimizing long-context embedding inference on Cloud TPU with vLLM
Google details how native TPU support in vLLM enables elastic scaling and high-precision embedding inference for Qwen3 models.
Daily coverage of AI, developer tools and infrastructure. Each story explains what happened and why it matters, with a link to the original source.
Google details how native TPU support in vLLM enables elastic scaling and high-precision embedding inference for Qwen3 models.
Kubernetes lacks native support for partial device failures, forcing engineers to build custom remediation logic for expensive AI and ML training jobs.
The Kubernetes project released the Gateway API Inference Extension to standardize routing for generative AI workloads, reducing latency and improving GPU utilization.
Kubernetes v1.33 introduces a new verification mechanism to prevent unauthorized pods from reusing private container images already present on a node.
Kubernetes v1.33 adds streaming encoding for List responses, reducing kube-apiserver memory usage by up to 20x during large dataset fetches and improving cluster stability.
Kubernetes v1.32 re-enables the QueueingHint feature by default, allowing plugins to precisely determine when unschedulable pods should be retried, reducing wasted scheduler cycles.
A technical guide details how to construct a self-hosted cloud platform using Kubernetes, Talos Linux, and GitOps tools to manage bare metal infrastructure.
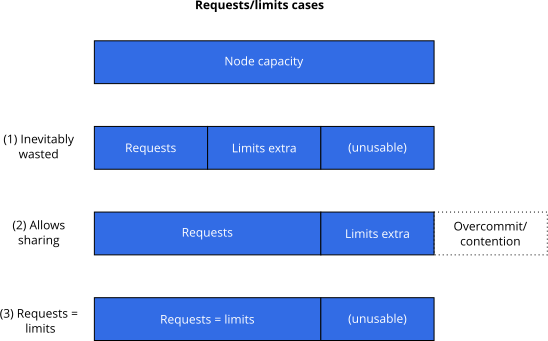
A 2023 analysis argues that setting CPU and memory limits in Kubernetes improves performance predictability, even if it reduces raw cluster efficiency.
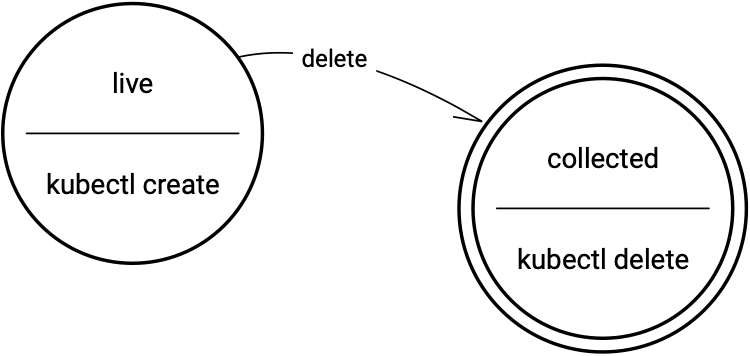
A 2021 guide explains how finalizers block resource removal and how owner references manage cascading deletes in Kubernetes clusters.