How controller-runtime cache prevents API server overload
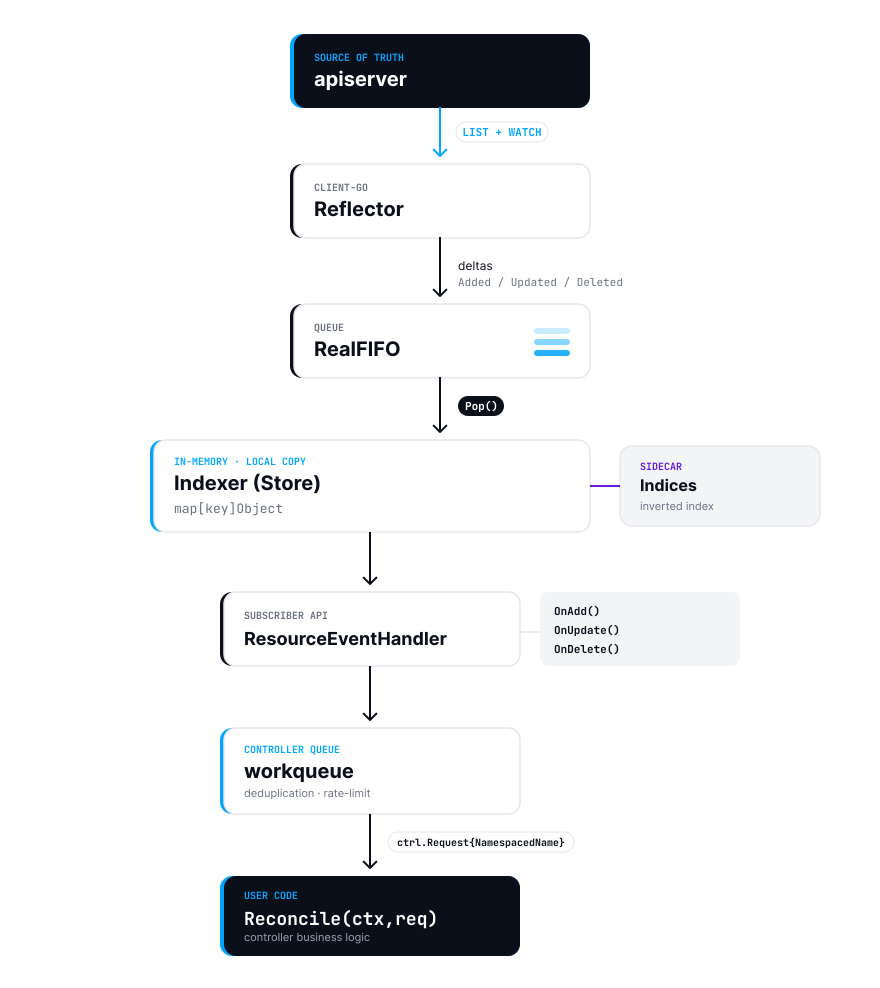
A deep dive into the list-watch pattern and local caching in Kubernetes controllers, explaining why reads are cheap but consistency is eventual.
Daily coverage of AI, developer tools and infrastructure. Each story explains what happened and why it matters, with a link to the original source.
A deep dive into the list-watch pattern and local caching in Kubernetes controllers, explaining why reads are cheap but consistency is eventual.
The Kubernetes project released the Gateway API Inference Extension to standardize routing for generative AI workloads, reducing latency and improving GPU utilization.
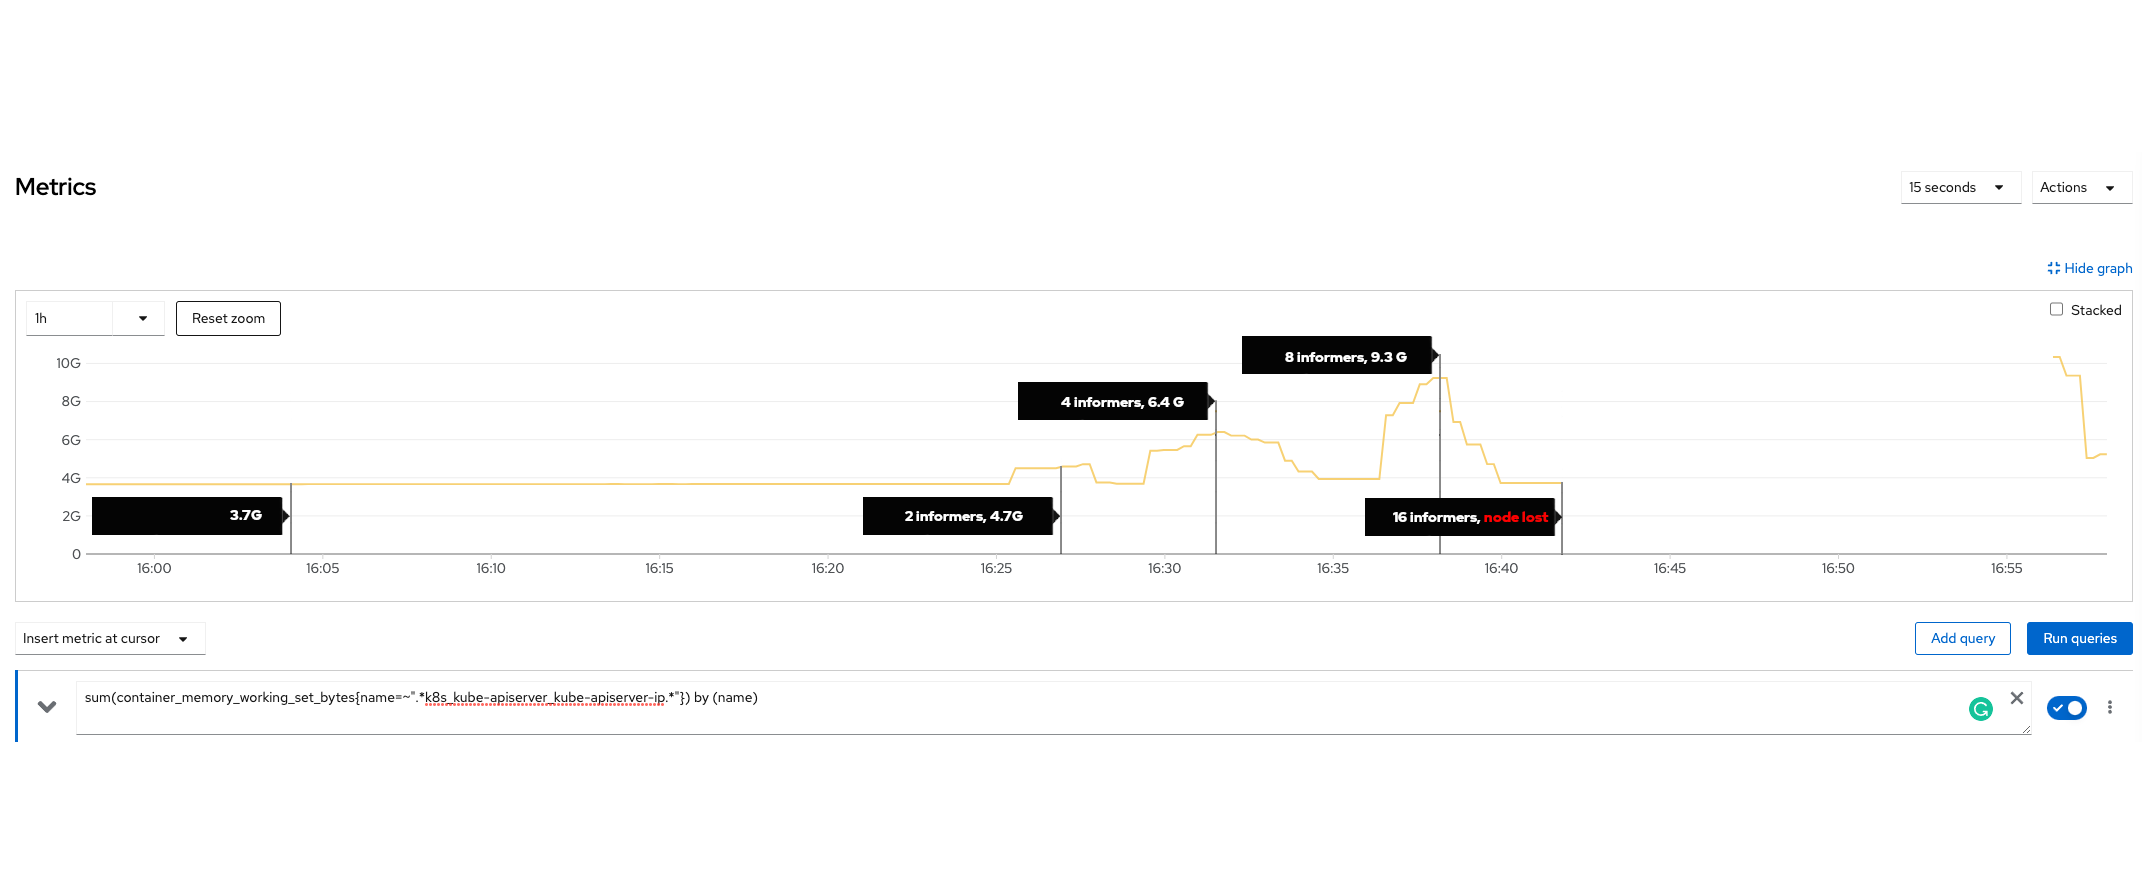
Kubernetes v1.33 adds streaming encoding for List responses, reducing kube-apiserver memory usage by up to 20x during large dataset fetches and improving cluster stability.
Kubernetes 1.32 graduates watch lists to beta, allowing clients to stream large resource collections and prevent API server out-of-memory crashes.
Cozystack engineers explain how they used the Kubernetes API aggregation layer to create dynamic, imperative endpoints and bypass etcd storage limitations.
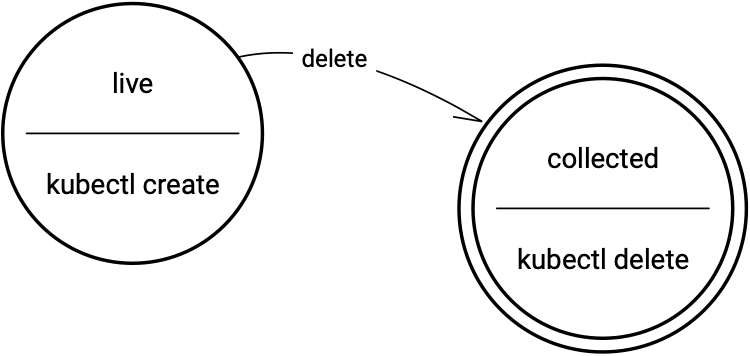
A 2021 guide explains how finalizers block resource removal and how owner references manage cascading deletes in Kubernetes clusters.